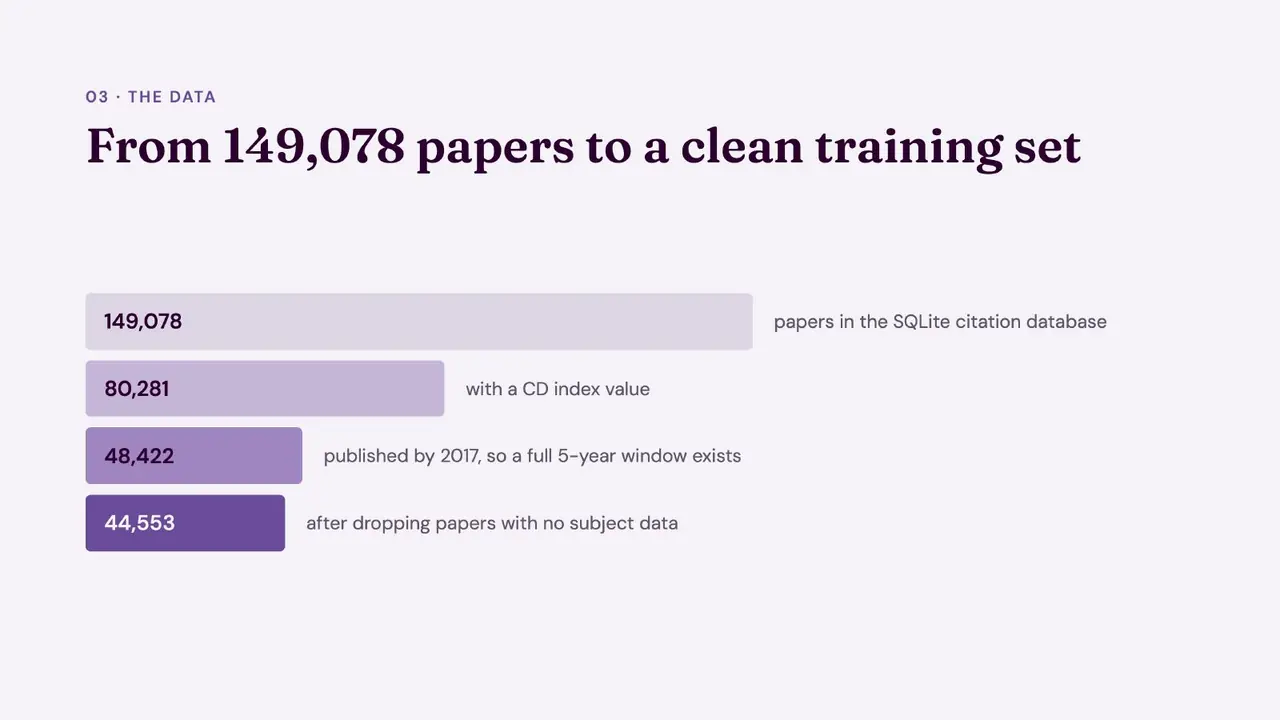
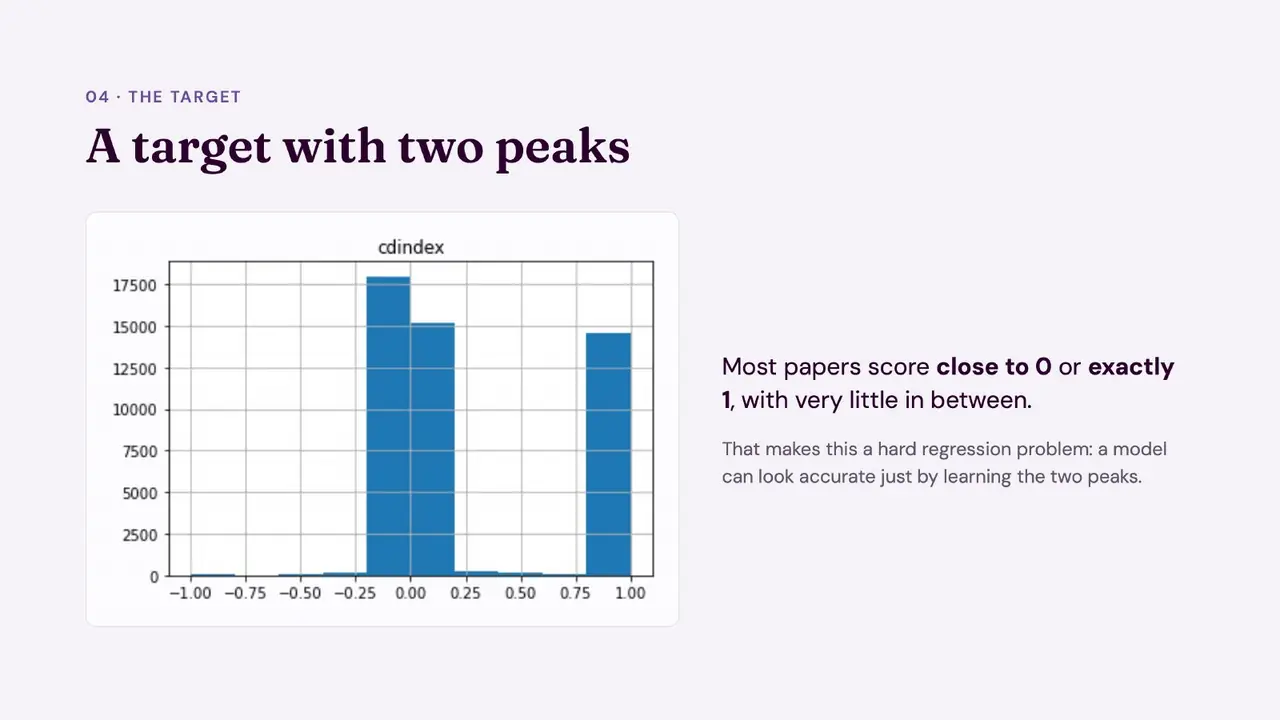
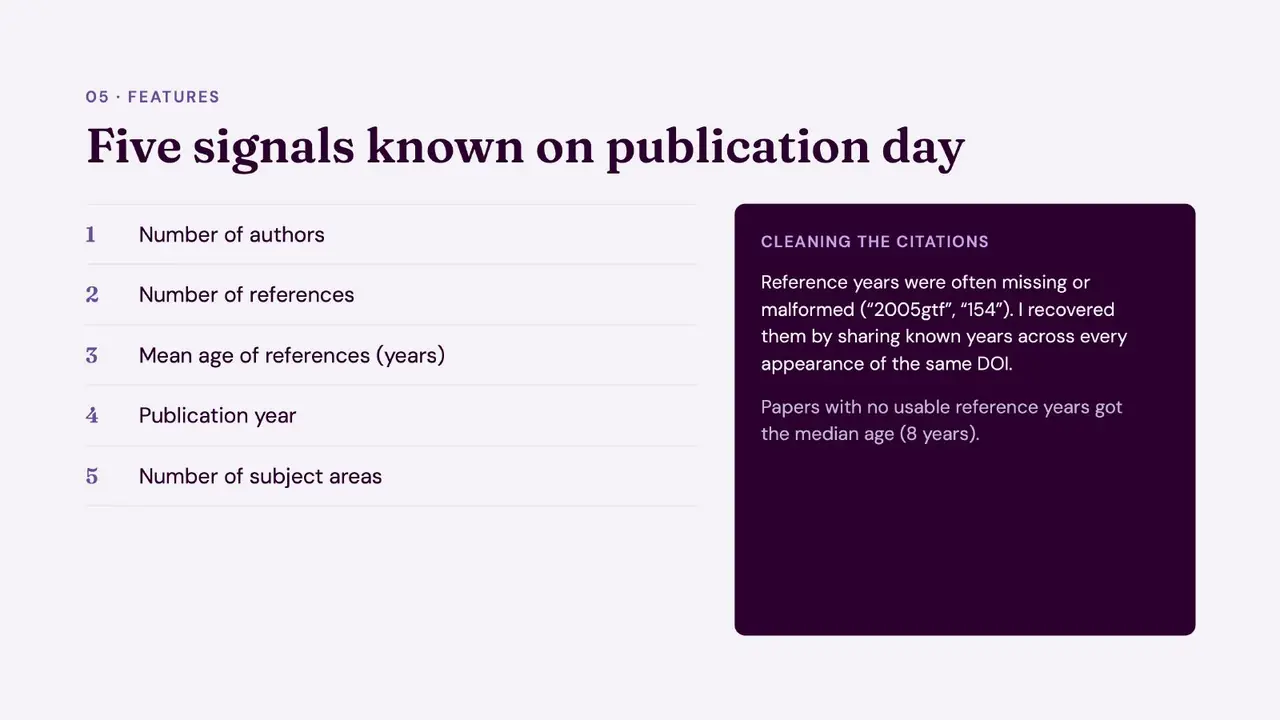
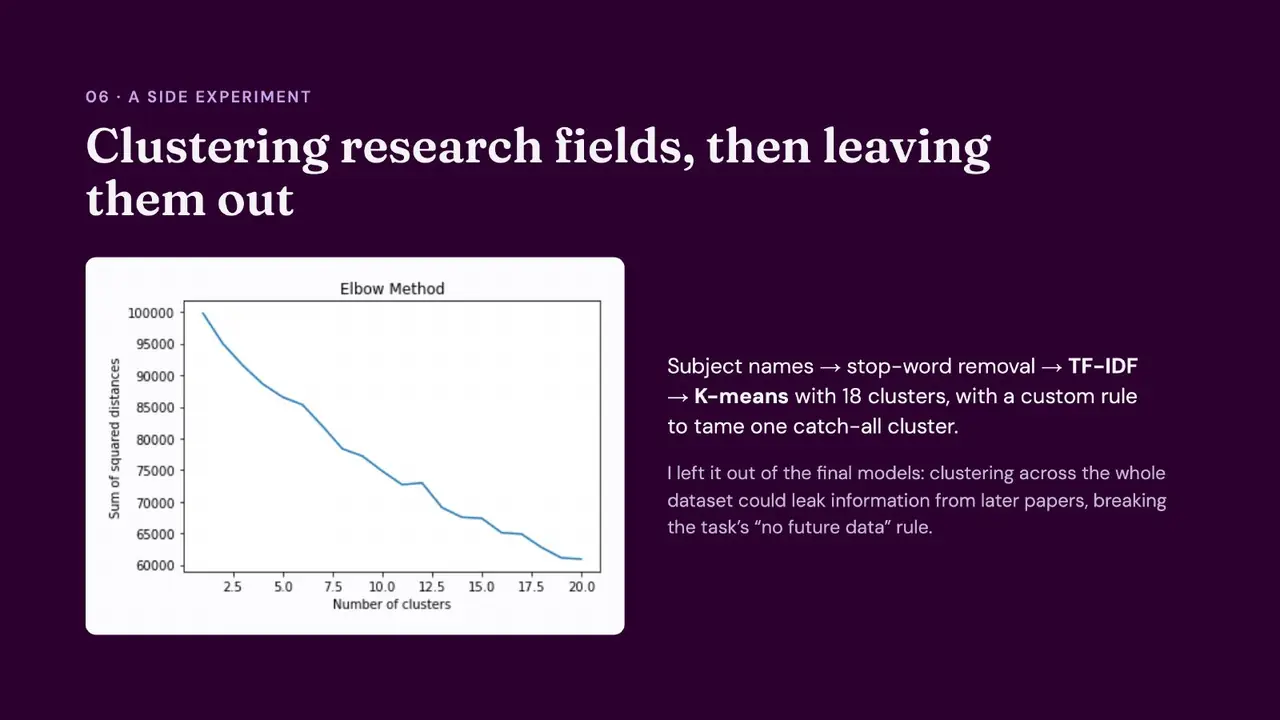
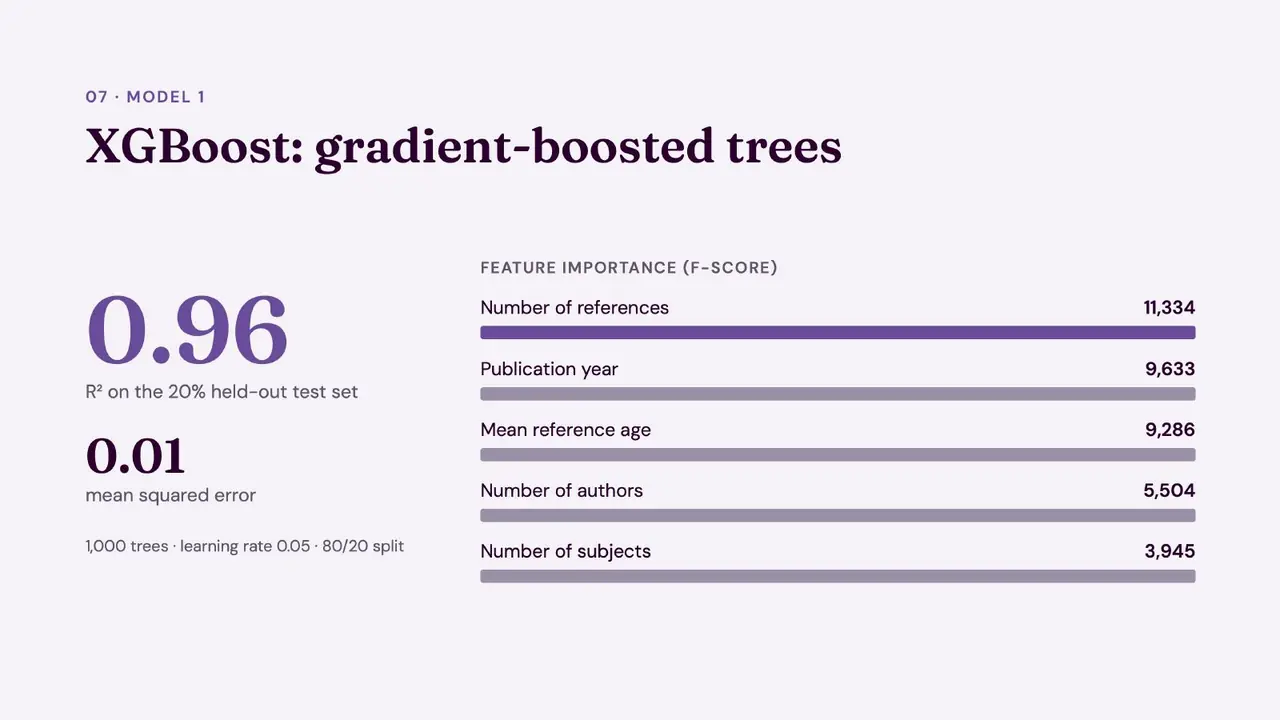
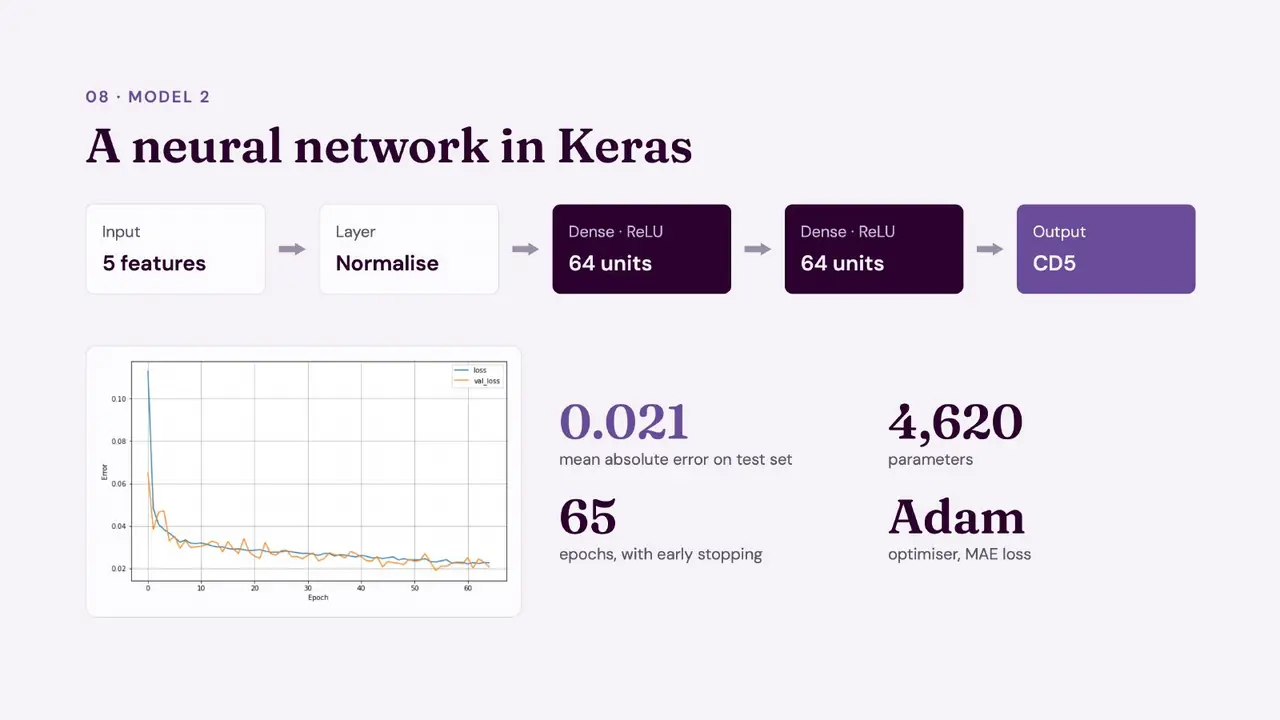
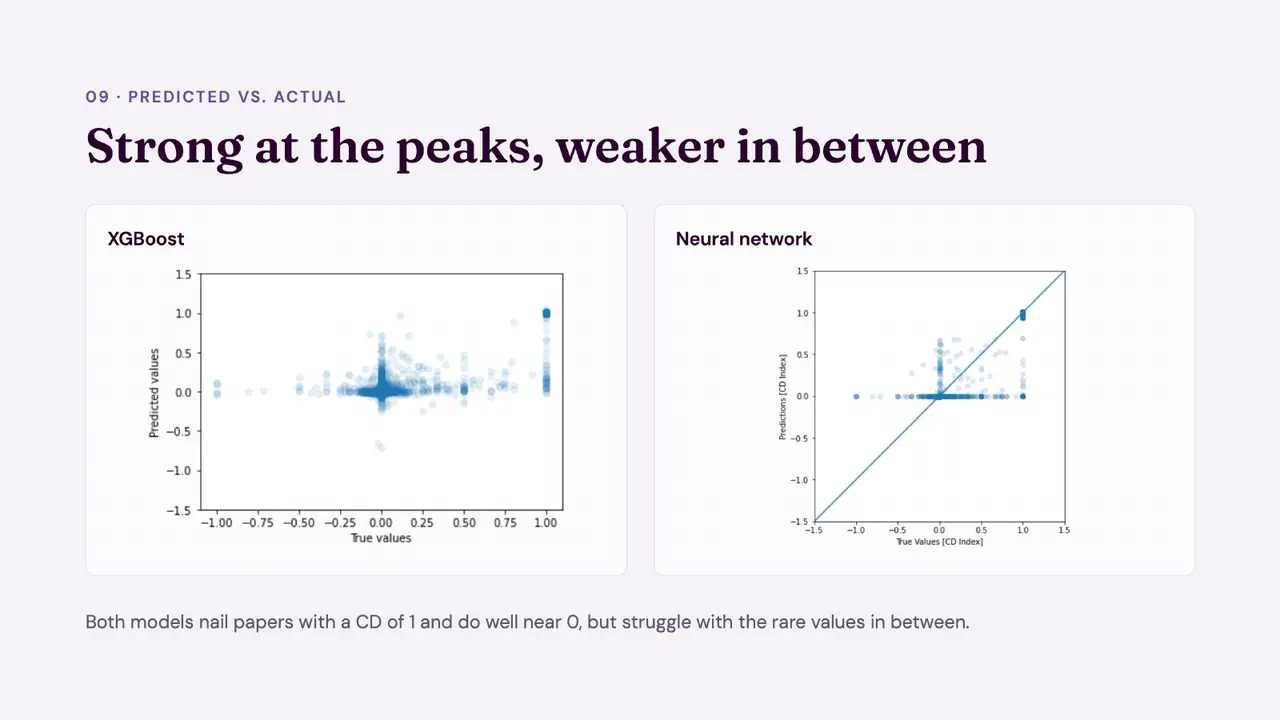
I cut a 149,078-paper SQLite citation database down to 44,553 clean training papers and built five features known at publication: authors, references, mean reference age, publication year and number of subject areas. Messy reference years were recovered by sharing known years across every appearance of the same DOI. I trained gradient-boosted trees (XGBoost) and a two-layer Keras network. I also clustered research fields with TF-IDF and K-means, but left it out of the final models because it could leak information from later papers.